Over the last couple of years, building an AI assistant has become relatively straightforward: pick an LLM, write a prompt, and embed a chatbot widget into a website or app.
But in real business deployments, teams quickly discover the hard part isn’t “making it answer” — it’s solving three practical problems:
- What exactly does the assistant know?
- How up-to-date is that knowledge?
- How do you guarantee predictable behavior — without hallucinations, strange recommendations, or sending users to competitors?
That’s why the core asset of a modern generative AI solution is not the chat UI. It’s context management:
- what sources are treated as truth;
- how they’re refreshed;
- how model freedom is constrained with AI guardrails;
- what happens when the system doesn’t have enough data.
Why context in AI matters more than prompt engineering
An LLM is probabilistic by nature. If you don’t provide a verifiable foundation, it will complete answers with what sounds plausible.
In business, that becomes AI hallucinations:
- made-up delivery terms;
- non-existent products;
- outdated prices;
- policy mistakes.
The winning approach is hybrid AI:
- Knowledge and context come from your sources: product catalogs, FAQs, policies and internal documentation.
- The model receives only the relevant excerpt and must respond strictly within allowed rules.
This is the approach implemented by Riserlabs as a service: you connect sources — URLs or files — and the system extracts structured knowledge and periodically synchronizes it, keeping answers grounded and current.
Why AI deployments become expensive — and how to shorten time-to-value
The “classic” route is to build your own RAG pipeline:
- ingestion jobs;
- embeddings;
- a vector database;
- retrieval and ranking;
- evaluation;
- monitoring;
- security;
- logging;
- cost controls.
It works — but it’s slow and expensive, especially when you’re still validating ROI.
Riserlabs focuses on fast rollout: launch an AI widget or connect via API, add one or two sources, and test with real users.
The platform is positioned to help teams validate the hypothesis more cheaply than building full RAG infrastructure from scratch — then scale scenarios, restrictions and governance.
Behavior control: make an AI sales rep sell, and AI support actually support
Even perfect knowledge is useless if the assistant behaves unpredictably.
Practical production-grade control requires the following.
Persona and rules
Define:
- tone of voice;
- boundaries;
- refusal policy;
- how strictly the assistant follows the provided context.
This turns “a chatbot” into a controlled AI sales assistant or a reliable AI customer support agent.
Controlled actions and CTAs
Buttons and next steps can be configured in the dashboard and executed server-side.
This reduces the risk of prompt injection and model “freestyling.”
Security and anti-bot protection
Real B2B production deployments require:
- domain allowlists;
- CAPTCHA;
- rate limits;
- message encryption;
- predictable spending.
Without these controls, AI systems often become difficult to operate safely in production.
Example: e-commerce assistant with live products, prices and comparisons
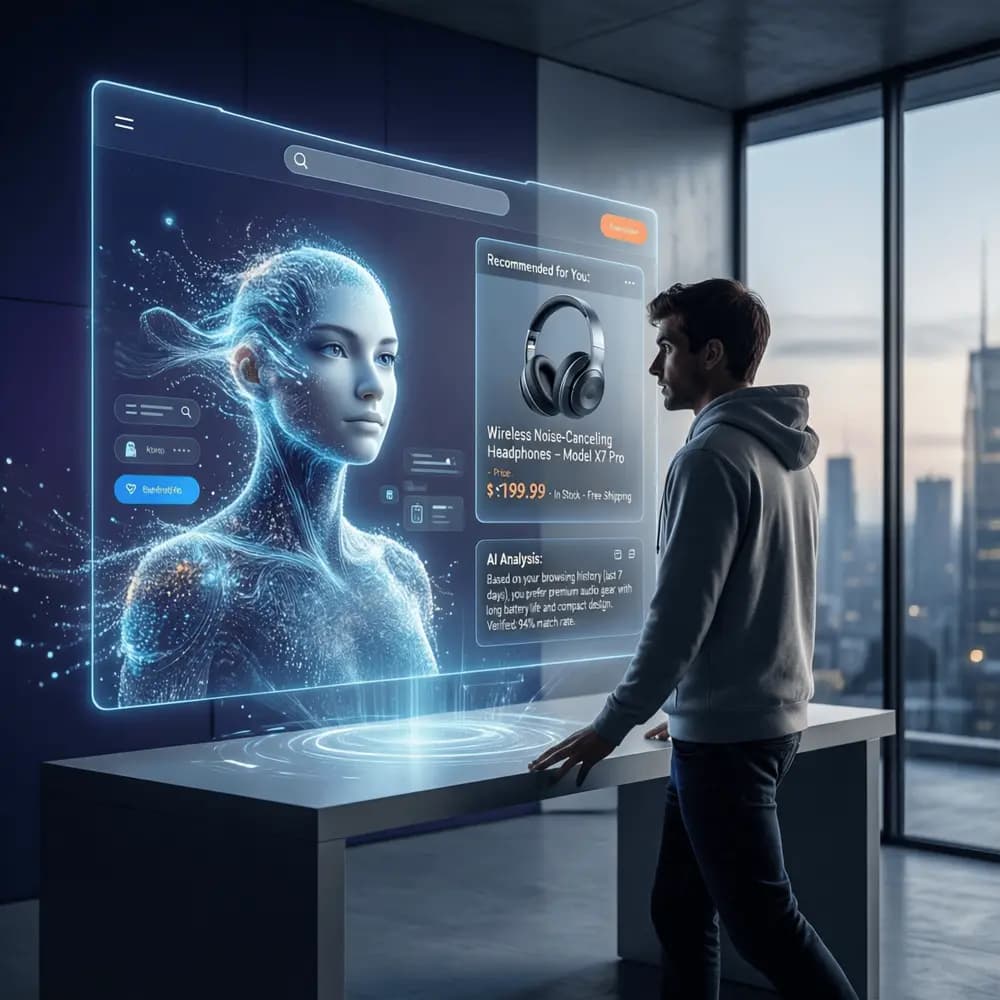
One of the most illustrative use cases is e-commerce AI.
Instead of “training the model on everything,” you connect your catalog as a source:
- URLs;
- files;
- YML feeds.
This works well with exports from Bitrix, Shopify and WooCommerce.
The catalog is refreshed regularly, and the assistant answers based on the data you provided:
- compares products;
- checks availability;
- uses current prices;
- guides users to purchase;
- avoids inventing information.
The takeaway
Today, the competitive advantage isn’t “having a chat.”
It’s the ability to quickly and safely assemble context, keep it up to date, and enforce predictable behavior.
That’s what makes it realistic to launch an AI assistant on riserlabs.io in tens of minutes — without building heavy infrastructure and without endless iterations of:
Why is it hallucinating again?